
AWS Certified AI Practitioner · Free Practice Question Medium
Question 27
An e-commerce company uses a chatbot powered by Amazon Bedrock to handle customer inquiries and assist with orders. To enhance customer satisfaction, the company wants the chatbot to continuously learn and improve from real-time customer interactions, adapting its responses to become more accurate and effective over time.
Which approach would be the most suitable for enabling ongoing self-improvement of the chatbot based on its conversations with customers?
-
A
The company should leverage reinforcement learning (RL), where rewards are generated from positive customer feedback to train the chatbot in optimizing its responses
-
B
The company should leverage transfer learning, which involves applying knowledge gained from one domain to enhance performance in another related domain
-
C
The company should leverage incremental training, a method that allows the chatbot to adapt over time by learning from new data without forgetting previously learned information
-
D
The company should leverage supervised learning, using the latest datasets containing both positive and negative customer interactions to improve the chatbot's response quality
Reveal correct answer
Correct answer: A
Explanation
Correct option:
The company should leverage reinforcement learning (RL), where rewards are generated from positive customer feedback to train the chatbot in optimizing its responses
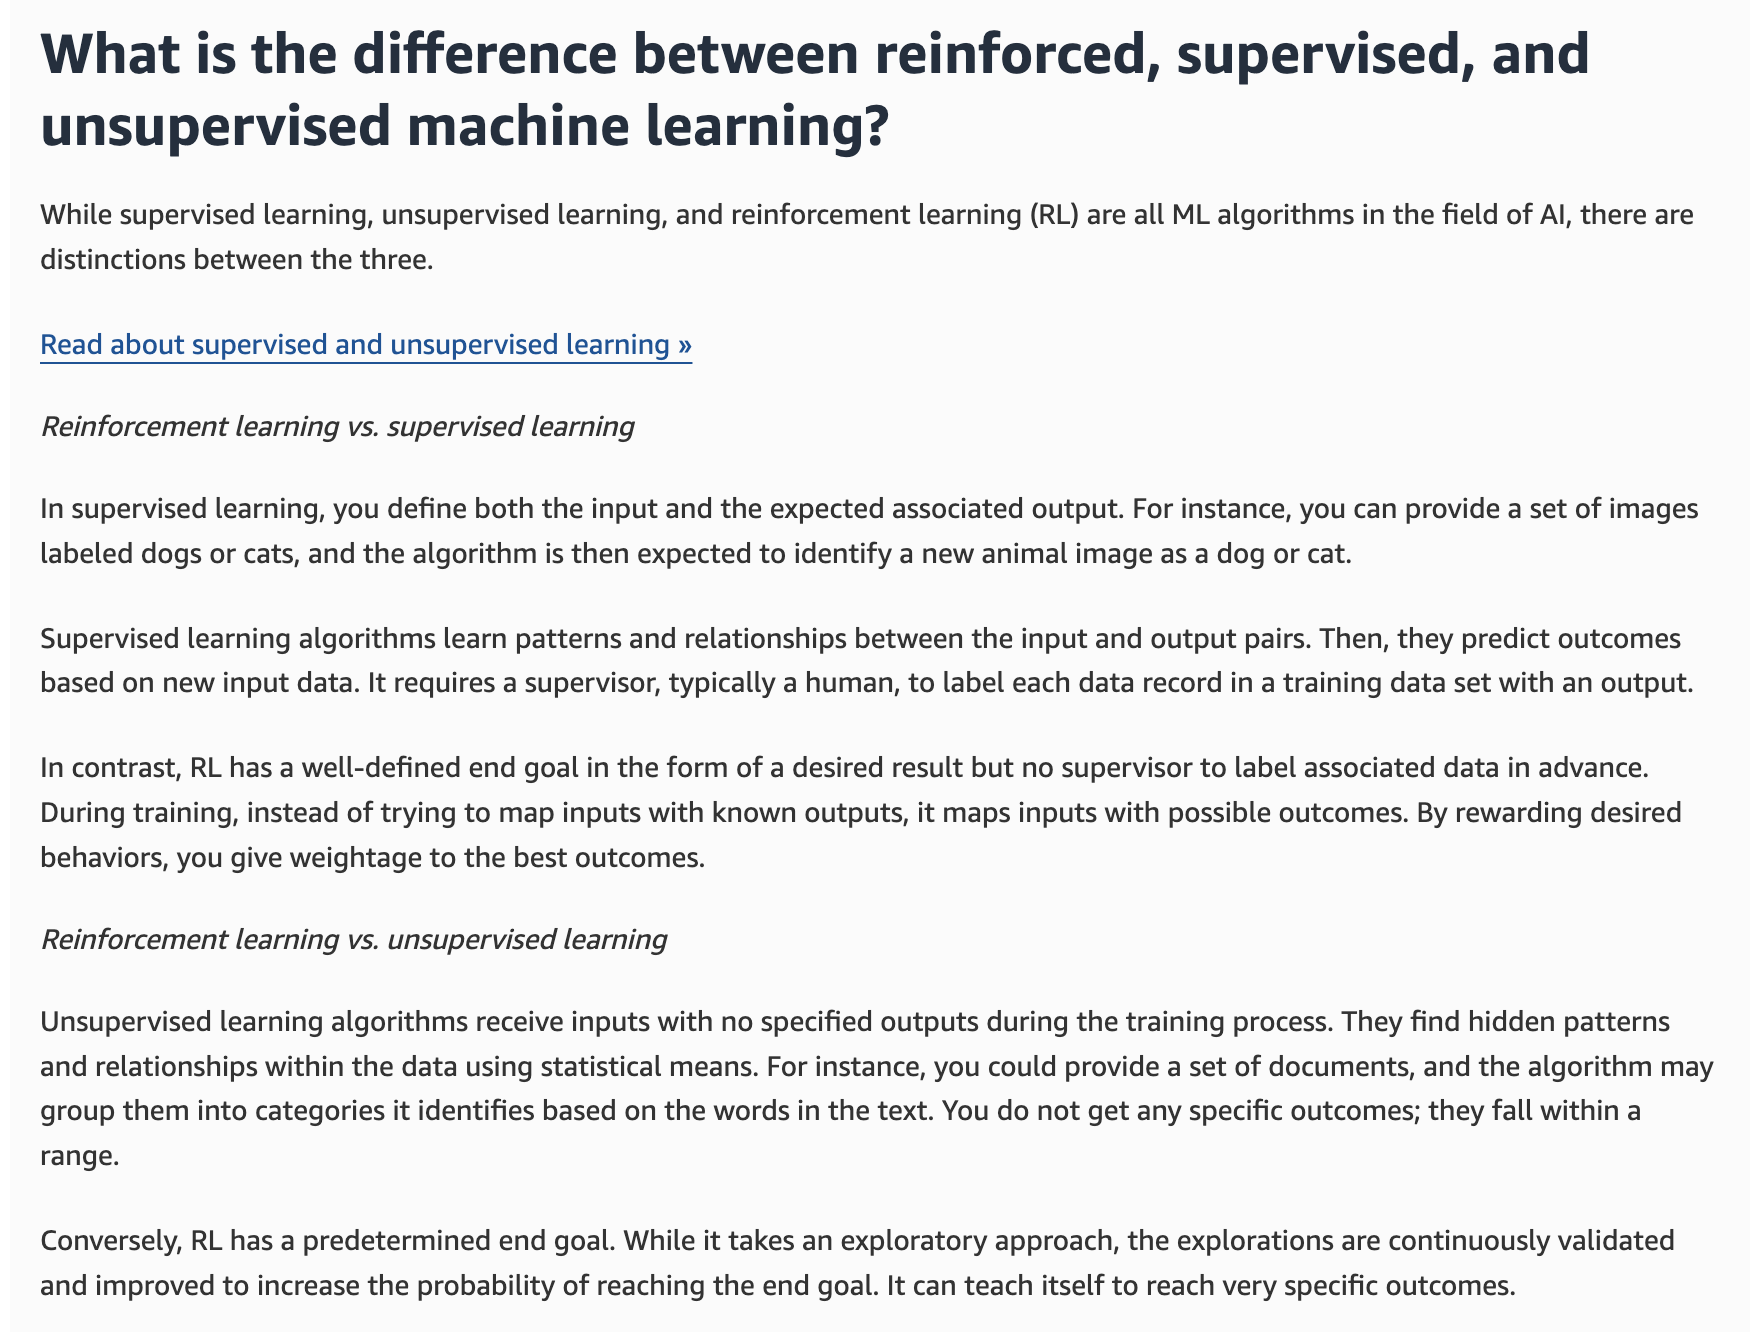
Reinforcement learning is the most suitable approach for self-improvement in this context. By leveraging RL, the chatbot can learn from customer interactions in real-time. Positive customer feedback serves as a reward signal that guides the chatbot to improve its responses over time. The chatbot adapts its behavior based on rewards or penalties, refining its conversational skills through continuous feedback loops. This dynamic learning process is effective for environments where responses need to be optimized based on direct user interaction and satisfaction.
Incorrect options:
The company should leverage supervised learning, using the latest datasets containing both positive and negative customer interactions to improve the chatbot's response quality - While supervised learning can be effective for training chatbots with labeled data (such as examples of positive and negative customer interactions), it is not ideal for ongoing self-improvement. Supervised learning requires extensive datasets and retraining the model whenever new data is available, making it less adaptive in real-time environments. Additionally, this approach does not directly learn from the immediate feedback provided by customers, which is crucial for dynamic improvement.
The company should leverage incremental training, a method that allows the chatbot to adapt over time by learning from new data without forgetting previously learned information - Incremental training allows a model to update itself with new data while retaining knowledge from old data. However, it may not be sufficient for optimizing chatbot performance in real-time, especially without incorporating direct feedback signals like those in reinforcement learning. Incremental learning is less dynamic than reinforcement learning and may struggle to keep up with fast-changing customer preferences or conversation styles.
The company should leverage transfer learning, which involves applying knowledge gained from one domain to enhance performance in another related domain - Transfer learning is used when a model trained in one domain or task can benefit from applying its knowledge to a different but related domain. While transfer learning can improve chatbot performance by leveraging pre-trained models, it does not provide the framework for continuous, self-improvement based on ongoing customer interactions. Therefore, it is not the most effective approach for a chatbot seeking to improve through real-time conversations.
References:
https://aws.amazon.com/what-is/reinforcement-learning/
https://aws.amazon.com/what-is/machine-learning/
https://aws.amazon.com/blogs/machine-learning/incremental-training-with-amazon-sagemaker-jumpstart/
Discussion
Think the marked answer is wrong, or have a better explanation? Share it below — comments appear after review.

